
Working with log files and large text files often means dealing with repeated data, unsorted entries, and difficult-to-read output. Linux provides two simple yet powerful tools for this task: sort and uniq.
In this tutorial, you’ll learn how the sort and uniq commands work, why they are commonly used together, and how to use them for real-world tasks such as analyzing log files, counting repeated entries, and removing duplicates from text files.
Prerequisites
- A Linux system (or macOS terminal with these commands available)
- Basic familiarity with the command line
- Permission to read the log files used in the examples
- Understanding sort and uniq
Before jumping into the examples, it’s important to understand what each command does.
What Does the sort Command Do?
The sort command rearranges lines of text into a specific order. By default, it sorts lines alphabetically from A to Z.
sort filename.txtIt can also sort numerically, reverse the output order, or sort by specific columns using additional options.
What Does the uniq Command Do?
The uniq command filters or counts duplicate lines. A common beginner mistake is assuming uniq removes every duplicate automatically. In reality, it only works on adjacent matching lines.
For example:
- apple
- banana
- apple
Because the two apple entries are not next to each other, uniq will not detect them as duplicates.
Why sort and uniq Are Usually Used Together
To make duplicate entries appear side by side, the file is usually sorted first.
sort filename.txt | uniqThe pipe (|) sends the output from sort directly into uniq.
This combination:
- Sorts the content.
- Groups identical lines together.
- Removes duplicate entries.
- Count Duplicate Entries
To display how many times each line appears, use the -c option:
sort filename.txt | uniq -c
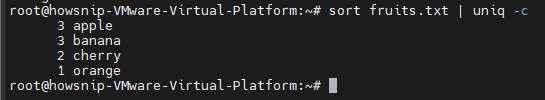
Example output:
- 3 apple
- 2 banana
- 1 orange
The number at the beginning of each line represents the number of occurrences.
Example 1: Find Which IP Addresses Are Hitting Your SSH Server
On Debian and Ubuntu systems, failed SSH login attempts are typically recorded in:
/var/log/auth.logThe following command extracts source IP addresses from failed login attempts, counts them, and displays the most frequent offenders first.
grep "Failed password" /var/log/auth.log | awk '{print $11}' | sort | uniq -c | sort -rn
How This Command Works
- grep “Failed password” /var/log/auth.log – Filters the log to show only failed SSH login attempts.
- awk ‘{print $11}’ – Extracts the eleventh field, which typically contains the source IP address in the standard authentication log format.
- sort – Groups identical IP addresses together.
- uniq -c – Counts how many times each IP appears.
- sort -rn – Sorts the results numerically (-n) and in reverse order (-r), placing the highest counts at the top.
Example Output
- 218 203.0.113.45
- 142 192.168.1.105
- 87 10.0.0.22
- 9 198.51.100.4
The first column shows the number of failed login attempts, while the second column shows the IP address.
Important: Don’t forget the final sort -rn. Without it, the output will not be ranked from highest to lowest.
Example 2: Summarize Requested URLs in an Apache Access Log
Apache access logs typically store each HTTP request on a separate line, with the requested URL located in the seventh field.
Use the following command to identify the most requested URLs:
awk '{print $7}' /var/log/apache2/access.log | sort | uniq -c | sort -rn
What the Command Does
- Extracts the requested URL path from each log entry.
- Groups identical URLs together.
- Counts occurrences.
- Displays results from most requested to least requested.
This is useful for identifying:
- Popular pages
- Frequently accessed resources
- Unexpected traffic patterns
Example 3: Remove Duplicate Lines from a Text File
The sort command includes a built-in option called -u (unique), which combines sorting and duplicate removal in one step.
sort -u fruits.txt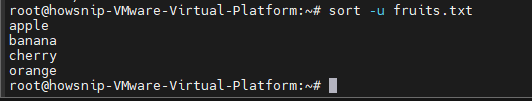
Sample File
- apple
- apple
- apple
- banana
- banana
- banana
- cherry
- cherry
- orange
Output
- apple
- banana
- cherry
- orange
Each value appears only once, and the results are sorted alphabetically.
Save the Cleaned Output to a New File
The original file is not modified automatically.
To save the deduplicated data:
sort -u fruits.txt > cleaned.txt
This writes the cleaned output into a new file called cleaned.txt.
Example 4: Display Only Duplicate Lines
Sometimes you don’t want to remove duplicates. Instead, you may want to identify which lines appear more than once.
Use the -d option with uniq:
sort access.log | uniq -d
What It Does
- Sorts the file first.
- Displays only duplicated lines.
- Hides unique entries.
This technique can help uncover:
- Repeated web requests
- Duplicate records
- Jobs running multiple times unexpectedly
Note: If the command produces no output, every line in the file is unique.
Example 5: Count Error Types in a Custom Application Log
Suppose your application log contains levels such as:
- ERROR
- WARN
- INFO
The following example counts each log level for a specific date:
grep "2025-04-18" /var/log/myapp.log | awk '{print $3}' | sort | uniq -c | sort -rn
Here,
- grep “2025-04-18” /var/log/myapp.log – Filters logs for a specific date.
- awk ‘{print $3}’ – Extracts the third field, which contains the log level in this example.
- sort | uniq -c | sort -rn – This command counts and ranks each log level by frequency.
Need to Find the Correct Field Number?
Preview the structure of your log file:
awk '{print $1, $2, $3, $4}' yourfile.log | head -5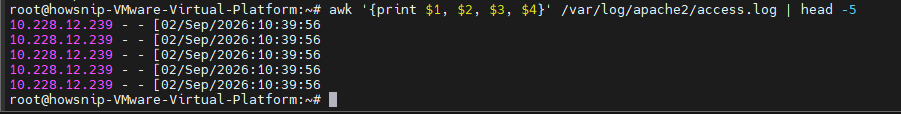
This displays the first few columns so you can determine which field contains the information you need.
Useful sort Command Options
These are the most commonly used sort flags:
- -r Reverse the sort order.
- -n Sort numerically instead of alphabetically.
- -u Output only unique lines.
- -k Sort using a specific field or column.
Examples
Sort numbers from largest to smallest:
sort -rn numbers.txtSort using the second column:
sort -k2 data.txtUseful uniq Command Options
The most practical uniq options include:
- -c Display occurrence counts.
- -d Show only duplicated lines.
- -u Show only unique (non-duplicated) lines.
- -i Ignore case when comparing lines.
Example
Ignore letter case when checking duplicates:
sort names.txt | uniq -iThis treats Apple, APPLE, and apple as the same value.
Common Mistakes to Avoid
a) Running uniq Without sort
This is the most common mistake.
Incorrect:
uniq file.txtIf identical entries are not adjacent, duplicates will remain.
Correct:
sort file.txt | uniq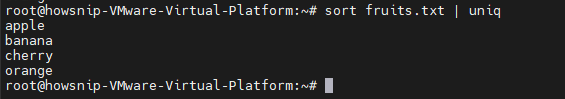
b) Using Numeric Sorting on Non-Numeric Data
The -n option should only be used when sorting numbers.
Correct example:
sort -n scores.txtc) Using numeric sorting on text data can produce unexpected results.
Assuming sort -u Changes the Original File
This command:
sort -u file.txtIt only displays output on the terminal.
To save the changes:
sort -u file.txt > cleaned.txtConclusion
The sort and uniq commands are essential Linux text-processing tools. Together, they make it easy to organize data, remove duplicate entries, count occurrences, and analyze large log files without writing custom scripts.
By understanding common options such as -c, -d, -u, -n, and -r, you can quickly transform raw logs and text files into clean, meaningful summaries that are much easier to work with.